#benchmarks
1 note tagged “benchmarks”. All notes →
-
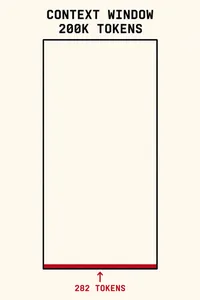
Benchmarks measure a model you are not running
agents
Terminal-Bench 4.0 tasks have a median of 394 tokens. SWE-bench Pro: 707. HumanEval: 117. Every major coding benchmark evaluates a model operating with essentially an empty context window — which is almost never the condition you run in. Unless you are running cattle.